
Azure HPC & AI infrastructure
19 posts, newest first.
#ai-infrastructure#alerts#application-insights#autoscaling#availability-zones#azure-batch#azure-compute#azure-compute-gallery#azure-files#azure-virtual-machines#azure-virtual-network#blob-storage#budgets#capacity-planning#checkpoints#cost-management#data-movement#deployment#dns#gpu#hpc#job-constraints#job-manager-task#jobs-and-tasks#linux#monitoring#mpi#node-errors#performance#powershell#quotas#rdma#start-task#start-tasks#subnet-planning#task-retries#telemetry#troubleshooting#virtual-file-mount#vm-sizing#workload-design
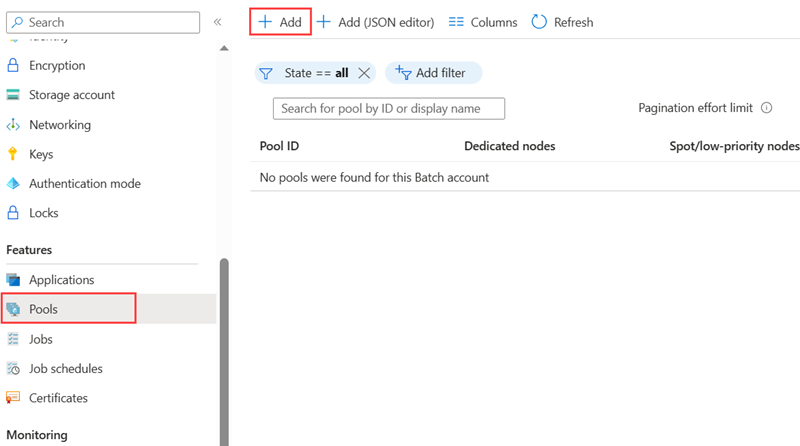 Review networking requirements before selecting an accelerator VM Plan Azure Batch networking for GPU pools by checking subnet IP capacity, storage tier limits, and communication modes before provisioning.
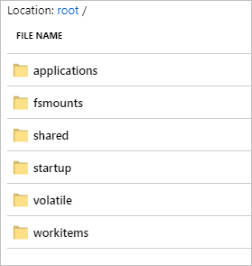 Separate job input data from temporary compute storage Plan checkpoint and restart behaviour for long-running jobs
All posts in this category
Investigate failed node startup in an Azure Batch pool 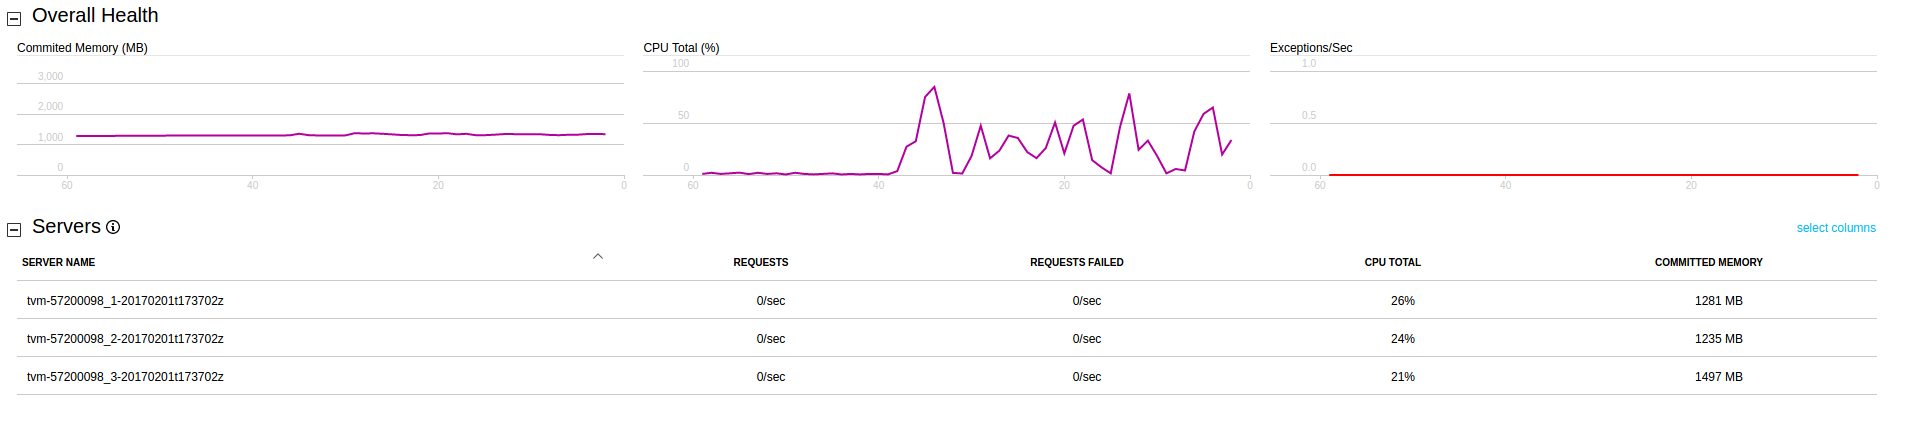 Monitor an HPC run without confusing observations and benchmarks Choose a placement approach for tightly coupled compute jobs Set a budget boundary around a compute experiment Plan data movement before moving an HPC workload to Azure
 Separate storage bottlenecks from compute bottlenecks Record GPU driver and library versions in a workload image Compare scale-up and scale-out for a compute workload Investigate an HPC job waiting for compute capacity Configure an Azure Batch pool for a repeatable compute job Plan shared storage access for an Azure HPC cluster Understand where an RDMA network helps an MPI workload Prepare a repeatable HPC compute image
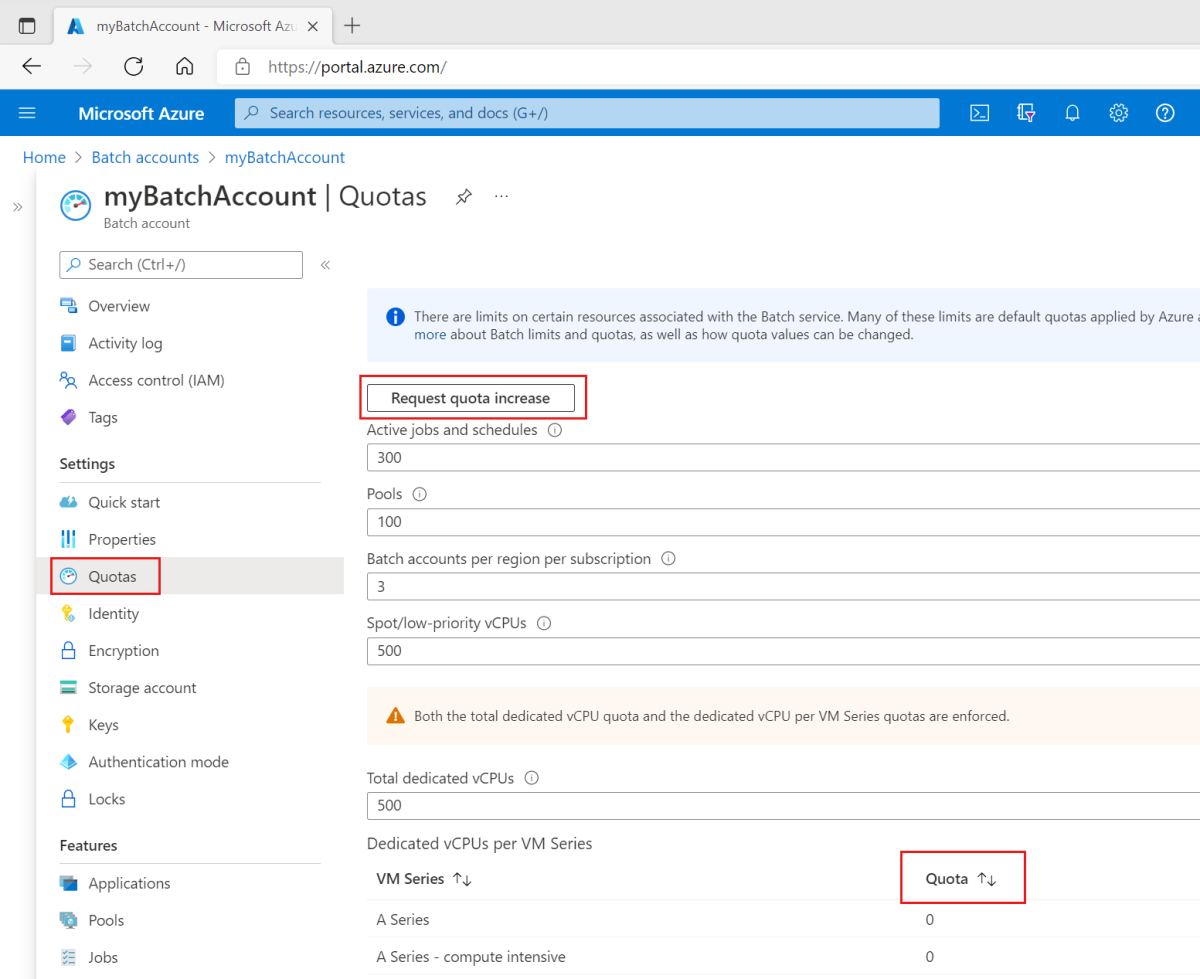 Check regional quota before planning a GPU deployment Choose CPU or GPU infrastructure for an AI workload Start an Azure HPC design with the workload requirements
Monitor an HPC run without confusing observations and benchmarks Choose a placement approach for tightly coupled compute jobs Set a budget boundary around a compute experiment Plan data movement before moving an HPC workload to Azure Separate storage bottlenecks from compute bottlenecks Record GPU driver and library versions in a workload image Compare scale-up and scale-out for a compute workload Investigate an HPC job waiting for compute capacity Configure an Azure Batch pool for a repeatable compute job Plan shared storage access for an Azure HPC cluster Understand where an RDMA network helps an MPI workload Prepare a repeatable HPC compute image Check regional quota before planning a GPU deployment Choose CPU or GPU infrastructure for an AI workload Start an Azure HPC design with the workload requirements