
#hpc
19 artigos, mais recentes primeiro.
 Review networking requirements before selecting an accelerator VM
 Separate job input data from temporary compute storage Plan checkpoint and restart behaviour for long-running jobs Investigate failed node startup in an Azure Batch pool
 Monitor an HPC run without confusing observations and benchmarks Choose a placement approach for tightly coupled compute jobs Set a budget boundary around a compute experiment Plan data movement before moving an HPC workload to Azure
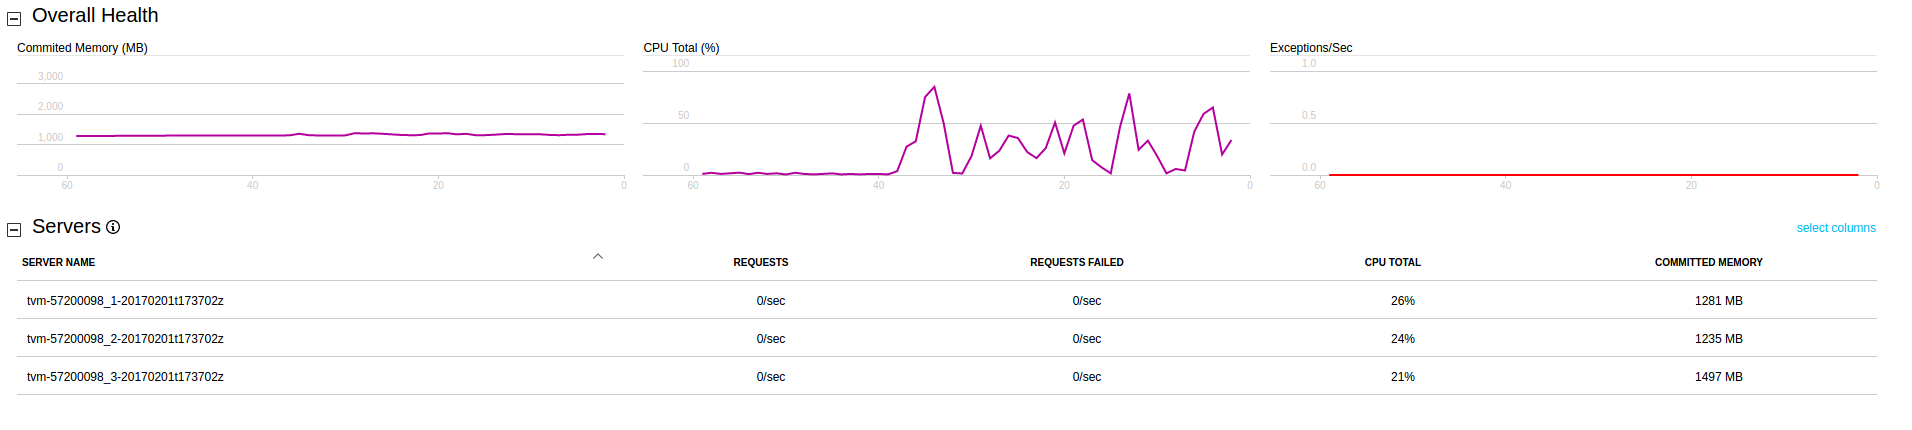 Separate storage bottlenecks from compute bottlenecks Record GPU driver and library versions in a workload image Compare scale-up and scale-out for a compute workload Investigate an HPC job waiting for compute capacity Configure an Azure Batch pool for a repeatable compute job Plan shared storage access for an Azure HPC cluster Understand where an RDMA network helps an MPI workload Prepare a repeatable HPC compute image
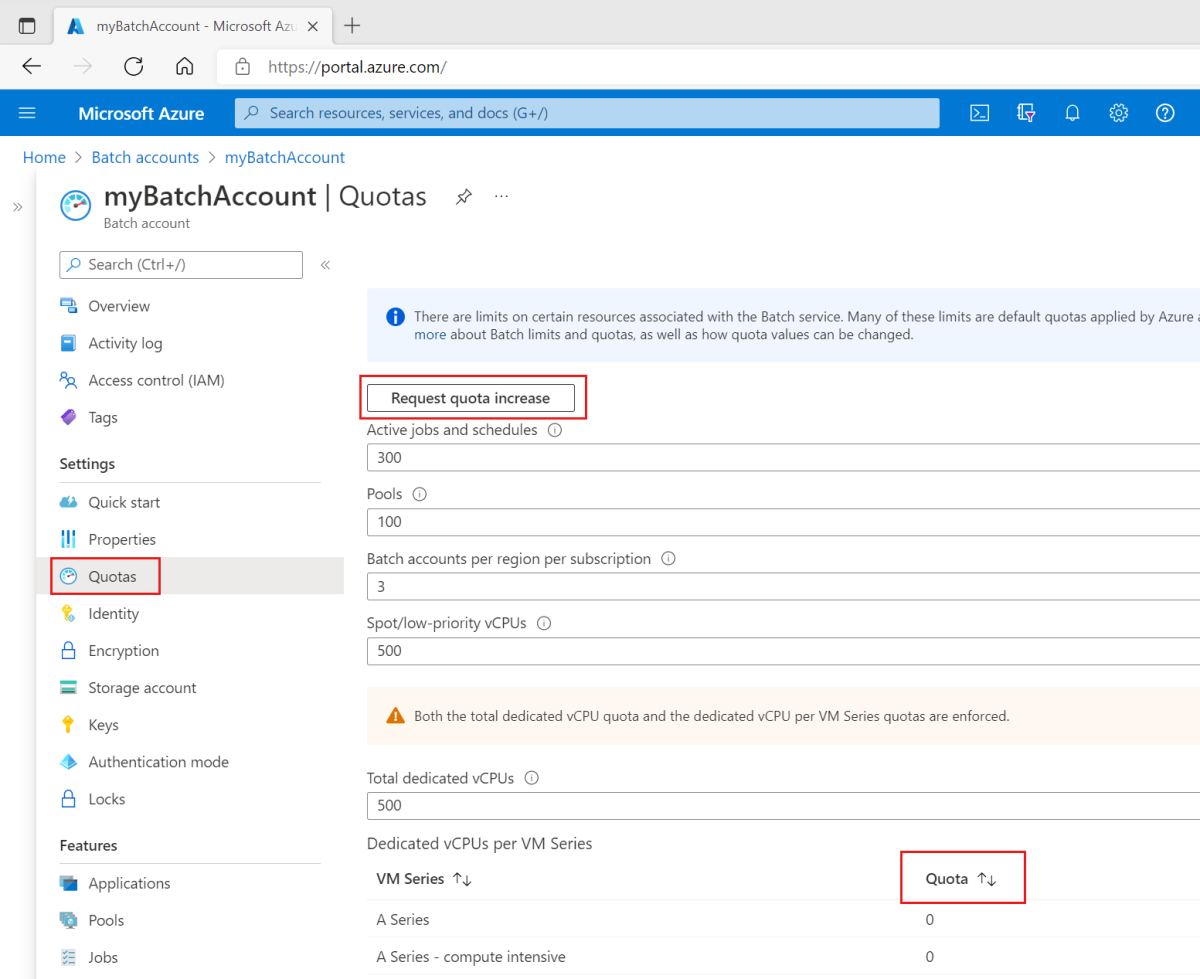 Check regional quota before planning a GPU deployment Choose CPU or GPU infrastructure for an AI workload Start an Azure HPC design with the workload requirements